
I am Yinda Chen (陈胤达), a Ph.D. candidate jointly trained by the University of Science and Technology of China (USTC) and the Shanghai AI Lab, majoring in Information and Communication Engineering. I expect to graduate in June 2027.
-
👀 My research connects representation and multimodal learning with embodied world models and agentic foundation models. I study how models learn useful representations, predict future states, and reason and act through interaction, with applications in robotics, biomedical imaging, and connectomics.
-
🧭 I am advised by Prof. Feng Wu (吴枫, CAE Academician, IEEE Fellow) and Prof. Zhiwei Xiong (熊志伟) at USTC. I was also co-supervised by Prof. Xiaoou Tang (汤晓鸥, IEEE Fellow) at Shanghai AI Lab in 2023. I work with Prof. Ruobing Zhang (张若冰) at Fudan University as my research mentor in connectomics and neuroscience.
More about my background and experience
-
🤝 My research collaborators and mentors include Prof. Dong Liu (刘东), Prof. Li Li (李礼), and Prof. Zhihai He (何志海, IEEE Fellow). I conducted research internships at Imperial College London with Dr. Rossella Arcucci and Dr. Che Liu (刘澈), and the PLA General Hospital (301 Hospital) with Prof. Qionghai Dai (戴琼海, CAE Academician, IEEE Fellow).
-
🌱 I am a core member at the Beijing Innovation Center of Humanoid Robotics (X-Humanoid), working on unified embodied models with Dr. Yong Dai (代勇). I was a core contributor to Pelican-Unified 1.0 and contributed to Pelican-VLA 0.5. Previously, I interned at Ubiquant (九坤投资), working on quantitative research and foundation models with thousand-GPU-scale training experience, including IQuest-Q1 and SAIL. At Tencent IEG, through the Qingyun Program, I worked on game world models and Honor of Kings – Lingbao, including text-to-speech and live match commentary, with Dr. Liang Du (杜量) and Dr. Wentao Yao (姚文韬).
-
💞️ I hold dual bachelor’s degrees in Environmental Ecological Engineering and Economics from Xiamen University, where I was advised by Prof. Yuanye Zhang (张原野). I began working on machine learning through WISER Club in 2021, introduced by Ziqian Lin (林子谦). This interdisciplinary background continues to shape how I approach research problems.
-
📝 My publications as first or co-first author include papers at ICCV, NeurIPS, AAAI, IJCAI, ICASSP, and MICCAI, and in TPAMI and JBHI. See the publications section or my Google Scholar profile
for details.
I welcome research discussions and collaboration on representation learning, embodied intelligence, agentic models, and connectomics. Please feel free to reach out.
🎯 Research Areas
🔥 News
- 2026.10 📄 IQuest-Q1 technical report released. I contributed to this agentic foundation model for CLI interaction, coding, and multi-step tool use during my research internship at Ubiquant (九坤投资).
- 2026.10 🔬 Core contributor to SAIL, a scientific-agent model for literature research, scientific coding, and multi-step research workflows at Ubiquant (九坤投资).
- 2026.10 🎉 Our paper GRCL was accepted by IEEE TPAMI.
- 2026.10 🏅 Selected for the 2026 CAST Doctoral Student Program (博士生青托) (CCF).
- 2026.08 🤖 Contributed to Tien Kung; see our team results at the World Humanoid Robot Games in Beijing.
- 2026.07 🤖 Pelican-VLA 0.5: Attending Before Acting Benefits Generalization technical report released. As the VLA component within Pelican-Unified, it uses learnable bottleneck tokens to connect task-relevant perception, future-frame generation, and action generalization.
- 2026.05 📈 Joined Ubiquant Investment (九坤投资) as a research intern, working on quantitative research and large language model foundation training.
- 2026.05 📄 Core contributor to Pelican-Unified 1.0, with work on unified vision-language modeling and action capability.
- 2026.04 🎵 Earned the Singing Popular Music certification from Berklee College of Music.
- 2026.01 🎓 Awarded the Zenghua Scholarship (增华奖学金) by USTC, a university-level scholarship.
- 2026.01 ✈️ Traveling to Singapore for AAAI 2026.
- 2025.12 💼 Joined Beijing Innovation Center of Humanoid Robotics (X-Humanoid) as a core member, focusing on embodied intelligence world models for humanoid robots.
- 2025.11 🎉 My advisor Prof. Feng Wu (吴枫) was elected as an Academician of the Chinese Academy of Engineering (CAE).
- 2025.08 💼 Started as Qingyun intern at Tencent IEG, working on game video scene understanding.
- 2025.06 📄 One paper was accepted by ICCV 2025.
- 2025.01 📄 One paper was selected as oral by AAAI 2025.
- 2024.12 🏅 Awarded the NSFC Doctoral Student Project (博士生国自然) as Principal Investigator, for the 2025–2027 project period.
- 2024.10 📄 One paper was accepted by NeurIPS 2024.
- 2022.10 🏆 Awarded the Graduate National Scholarship (研究生国家奖学金) at USTC.
📖 Education
🎓 Academic Background 3

University of Science and Technology of China & Shanghai AI Lab
Ph.D. candidate, Information and Communication Engineering
📍 Hefei & Shanghai · July 2024 - June 2027 (expected)
- Research focus: representation and multimodal learning, embodied world models, agentic foundation models, and connectomics.
- Advisors and research mentors: Prof. Feng Wu and Prof. Zhiwei Xiong; Prof. Xiaoou Tang (汤晓鸥, IEEE Fellow), co-supervisor at Shanghai AI Lab in 2023; Prof. Ruobing Zhang, connectomics and neuroscience mentor.
- Principal Investigator, NSFC Doctoral Student Project (awarded in 2024; project period 2025–2027; funding: RMB 300,000).
- Selected for the 2026 CAST Doctoral Student Program, with the China Computer Federation (CCF) as the cultivating society.
University of Science and Technology of China
M.S. in Computer Technology
📍 Hefei · Sept 2022 - July 2024

Xiamen University
Dual bachelor's degrees in Environmental Ecological Engineering and Economics
📍 Xiamen · Sept 2018 - July 2022
- Research advisor: Prof. Yuanye Zhang.
- Xiamen University Academic Star, 2021; CDA Level 1 certification, 2022; Kaggle Expert.
💼 Professional Experience
🏢 Industry Experience 4

Beijing Innovation Center of Humanoid Robotics (X-Humanoid)
Core Member, Embodied Intelligence World Model Team
📍 Beijing · Dec 2025 - Present
- Developing unified embodied models that connect scene and instruction understanding, future prediction, and robot action.
- Core contributor to Pelican-Unified 1.0, focusing on unified vision-language modeling and action capability.
- Contributed to Pelican-VLA 0.5, studying bottleneck representations for task-relevant perception and manipulation across scenes and embodiments.

Research Intern, Quantitative Research and Foundation Models
📍 Beijing · May 2026 - Oct 2026
- Worked on quantitative research and language models for factor mining and data-driven decisions, with experience in thousand-GPU-scale training.
- Contributor and co-author of IQuest-Q1, an agentic foundation model for CLI interaction, coding, and multi-step tool use (October 2026 technical report).
- Core contributor to SAIL, a scientific-agent model for literature research, scientific coding, and multi-step research workflows (October 2026).

Tencent Interactive Entertainment Group (IEG)
Qingyun Program Intern
📍 Shanghai · Aug 2025 - Dec 2025
- Developed multimodal scene understanding and game world models for gameplay analysis and content generation.
- Worked on Honor of Kings – Lingbao, including text-to-speech and live match commentary, with Dr. Liang Du and Dr. Wentao Yao.
- Contributed to MAIN-VLA, a world model for Game for Peace (和平精英) that connects intentions, game states, and actions.
- Researched router-free MoE-LoRA adaptation through linear aggregation and merging of low-rank expert updates.

PLA General Hospital (301 Hospital)
Research Intern, Data Compression Group
📍 Beijing · Sept 2023 - Feb 2024
- Collaborated with Prof. Qionghai Dai's team on medical image compression, designing methods adapted to different imaging modalities.
🎓 Academic Experience 3

Research Intern, Data Science Institute
📍 London (remote) · Nov 2022 - Aug 2023
- Worked with Dr. Rossella Arcucci and Dr. Che Liu on multimodal pretraining and image-text contrastive learning for medical images.
- This collaboration led to work including GTGM and BIMCV-R; see selected publications.
Academic Community Member, Data Mining Group
📍 Xiamen · Aug 2021 - July 2022
- Designed and delivered data mining courses on clustering and Transformers, and mentored undergraduate machine learning projects. Campus feature.
Wang Yanan Institute for Studies in Economics, Xiamen University
Research Assistant, Econometrics
📍 Xiamen · Aug 2020 - Dec 2021
- Assisted Jiong Zhu with land economic statistics research, using satellite imagery and visual features to study homesteads and land-use change.
📝 Selected Research
For a complete list of publications, please visit my Google Scholar profile
📈 View Citation Trend

Note: * denotes equal contribution. Journal and conference papers shown here are first- or co-first-authored; technical-report roles are stated individually.
🧠 Representation and Predictive Learning 3

TokenUnify: Scaling Up Autoregressive Pretraining for Neuron Segmentation
ICCV · 2025
Yinda Chen*; Haoyuan Shi*; Xiaoyu Liu; Te Shi; Ruobing Zhang; Dong Liu; Zhiwei Xiong; Feng Wu
Code  |
Dataset | Weights |
Autoregressive pretraining for volumetric neuron segmentation, combining three complementary prediction objectives with long-sequence modeling and an analysis of prediction-error accumulation.

Self-Supervised Neuron Segmentation with Multi-Agent Reinforcement Learning
IJCAI · 2023
Yinda Chen; Wei Huang; Shenglong Zhou; Qi Chen; Zhiwei Xiong
Code  |
Pretraining data |
Decision-based masked image modeling that learns masking policies through multi-agent reinforcement learning for neuron segmentation.

Learning Multiscale Consistency for Self-Supervised Electron Microscopy Instance Segmentation
ICASSP · 2024
Yinda Chen; Wei Huang; Xiaoyu Liu; Shiyu Deng; Qi Chen; Zhiwei Xiong

Self-supervised pretraining that encourages multiscale consistency in volumetric electron microscopy representations for neuron instance segmentation.
✨ Foundation Models, Multimodal Learning & Agents 8

Learned Image Coding with Generative Reference of Conditional Latents
IEEE TPAMI · Accepted October 2026
Siqi Wu*; Yinda Chen*; Weiming Chen; Dong Liu; K. C. Ho; Zhihai He
Code  |
GRCL uses retrieved or generated images as references for conditional latent coding. The framework combines reference generation, latent matching and synthesis, and theoretical analysis of robustness to reference perturbations.

Conditional Latent Coding with Learnable Synthesized Reference for Deep Image Compression
AAAI · 2025
Siqi Wu*; Yinda Chen*; Dong Liu; Zhihai He
| Code |
Weights |
Learnable reference synthesis from an external image dictionary improves conditional latent coding for learned image compression.

GTGM: Generative Text-Guided 3D Vision-Language Pretraining for Medical Image Segmentation
ICCV Workshop on VLM3D · 2025
Yinda Chen*; Che Liu*; Wei Huang; Xiaoyu Liu; Haoyuan Shi; Sibo Cheng; Rossella Arcucci; Zhiwei Xiong
Uses generated textual descriptions and negative-free contrastive learning to pretrain 3D medical image representations without paired medical text; evaluated through downstream segmentation on 10 CT/MRI datasets.

BIMCV-R: A Landmark Dataset for 3D CT Text-Image Retrieval
MICCAI · 2024
Yinda Chen; Che Liu; Xiaoyu Liu; Rossella Arcucci; Zhiwei Xiong
| Dataset | Code  |
A dataset of 8,069 3D CT volumes with paired radiology reports, together with the MedFinder framework for bidirectional medical image–text retrieval.

MaskFactory: Towards High-quality Synthetic Data Generation for Dichotomous Image Segmentation
NeurIPS · 2024
Haotian Qian*; Yinda Chen*; Shengtao Lou; Fahad Shahbaz Khan; Xiaogang Jin; Deng-Ping Fan
| Project | Code  |
A two-stage framework for generating paired images and masks for dichotomous image segmentation, expanding training data while preserving image–mask consistency.

EMPOWER: Evolutionary Medical Prompt Optimization With Reinforcement Learning
IEEE JBHI · 2025
Yinda Chen*; Yangfan He*; Jing Yang; Dapeng Zhang; Zhenlong Yuan; Muhammad Attique Khan; Jamel Baili; Por Lip Yee
Combines evolutionary prompt optimization with reinforcement learning and multi-dimensional evaluation for medical language tasks.
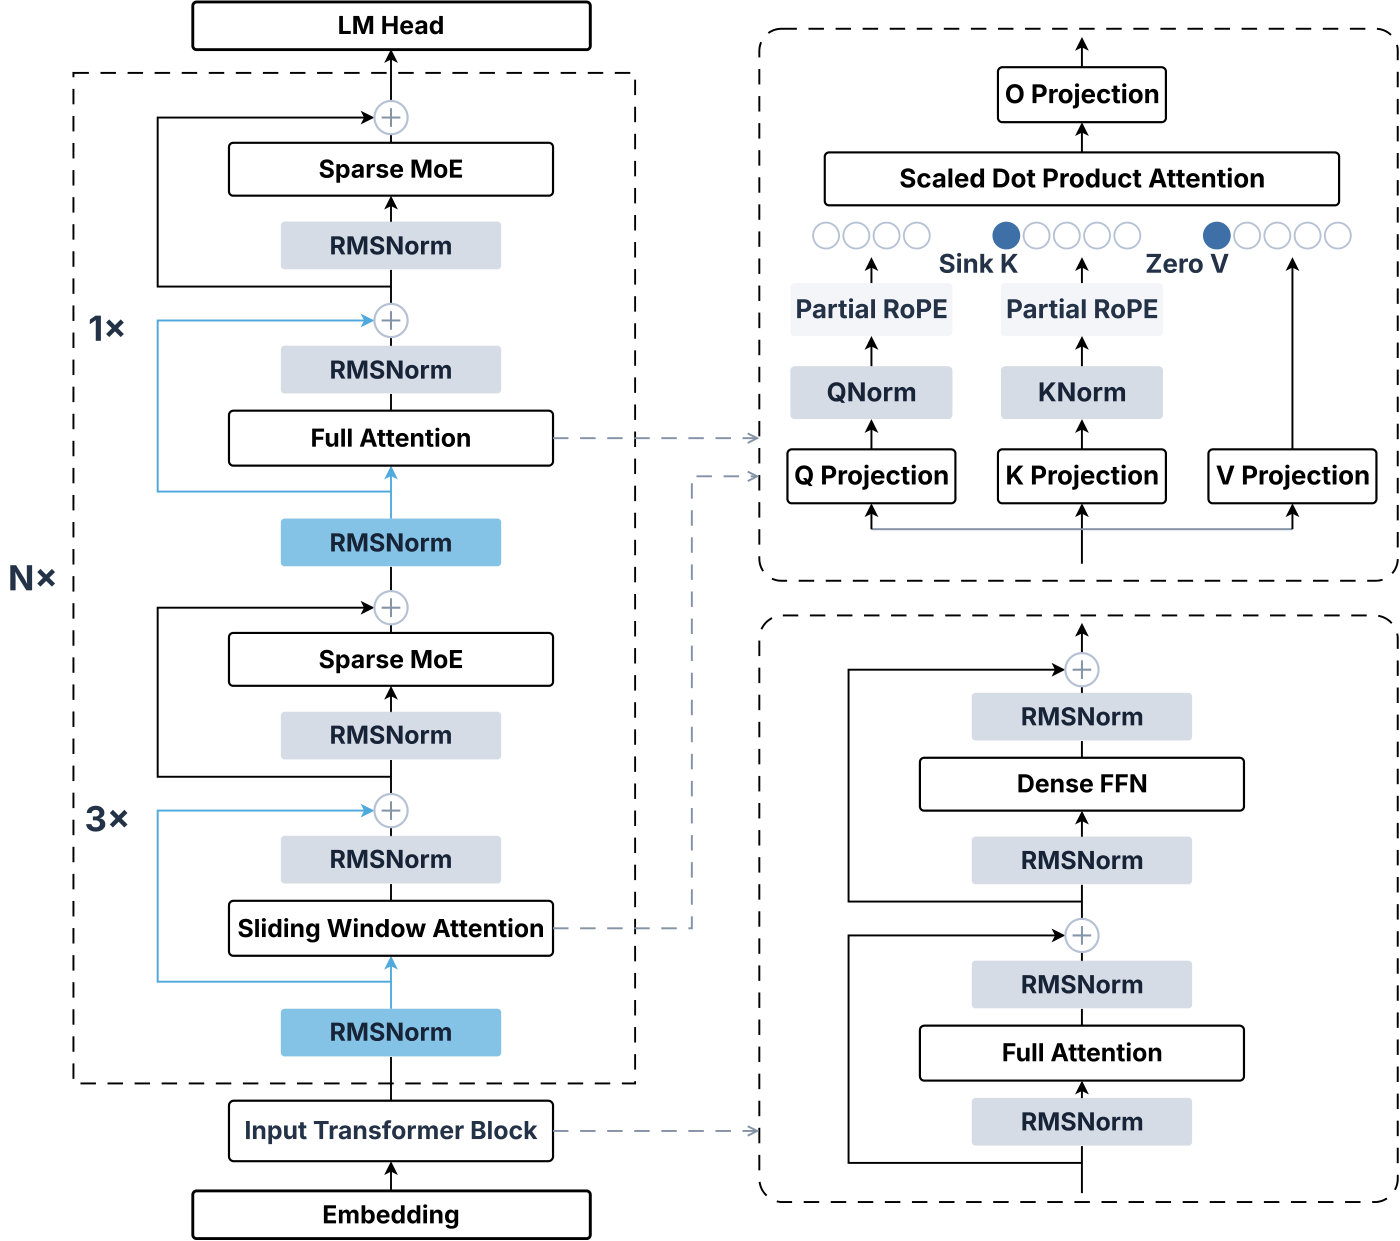
IQuest-Q1: Advancing Foundation Capabilities for Agentic CLI Systems
Ubiquant (九坤投资) · October 2026
Yinda Chen, co-author
| Report | Project | Code  |
Models |
A foundation model for command-line interaction, coding, and multi-step tool use. Contributed during my research internship at Ubiquant (九坤投资).
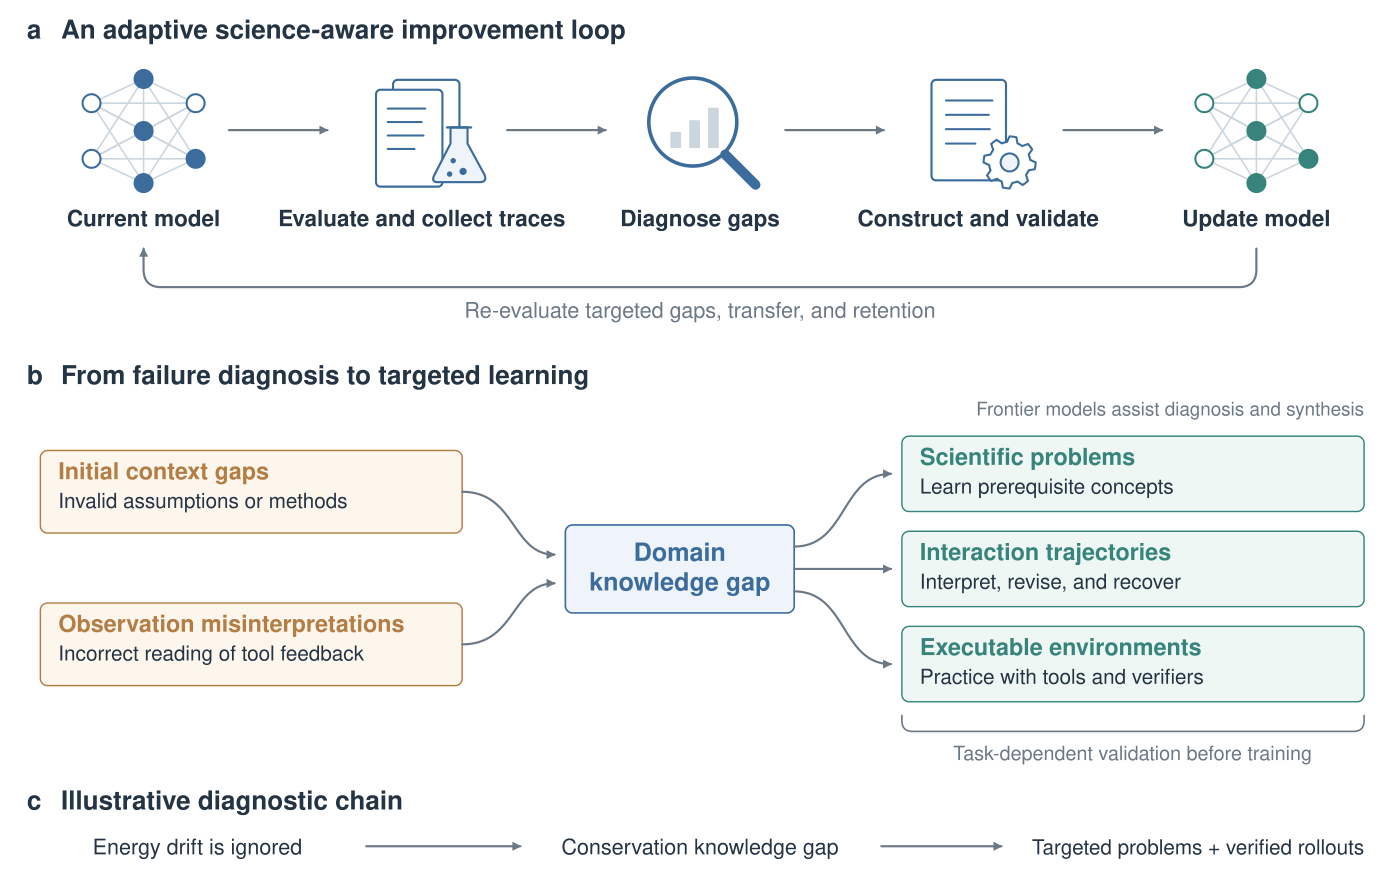
SAIL: Scientific Agentic Intelligence via a Science-Aware Loop
Ubiquant (九坤投资) · October 2026
SAIL Model Team · Yinda Chen, core contributor
A scientific-agent research project for literature research, scientific coding, and multi-step investigations, developed through a science-aware improvement loop.
🤖 World Models and Embodied Intelligence 2

Pelican-Unified 1.0: A Unified Embodied Intelligence Model (UEI) for Understanding, Reasoning, Imagination and Action
X-Humanoid, WFM System Group · May 2026
Pelican-Unified Team · Yinda Chen, core contributor
| Report | Organization |
My contribution: unified vision-language modeling and action capability.
A unified embodied model that combines scene and instruction understanding, task reasoning, and joint prediction of future video and robot actions.

Pelican-VLA 0.5: Attending Before Acting Benefits Generalization
X-Humanoid, WFM System Group · July 2026
Pelican-VLA Team · Yinda Chen, contributor
| Report | Code  |
Models |
The VLA component of Pelican-Unified connects vision-language understanding, future-frame generation, and action prediction through learnable bottleneck tokens. The work studies task-relevant attention and manipulation generalization.
🥇 Honors and Awards
🏅 National Awards & Research Funding 6
- 2026 CAST Doctoral Student Program (中国科协博士生青托) (October 2026)
- Cultivating society: China Computer Federation (CCF, 中国计算机学会)
- NSFC Doctoral Student Project (国家自然科学基金博士生项目) (December 2024)
- Role: Principal Investigator
- Project: Awarded in 2024; project period 2025–2027; funding of RMB 300,000
- Interdisciplinary Contest in Modeling (ICM), Outstanding Winner (May 2024)
- Competition: International mathematical modeling competition organized by COMAP
- Resources: 📝 Paper & Code
- National Graduate Scholarship (国家奖学金) (2022)
- Reference: 🔗 Official Announcement
- National Undergraduate Mathematics Competition (Non-Mathematics Majors), Second Prize (May 2021)
- Competition: National finals organized by the Chinese Mathematical Society
- Progress: Advanced from first place in the Fujian regional round
- Reference: 🔗 Competition News
- National Undergraduate Mathematics Competition, First Place in Fujian (November 2020)
- Category: Non-mathematics majors, Fujian regional round
- Ranking: First Place in Fujian Province


🎓 Academic Honors & Scholarships 2
- Zenghua Scholarship (增华奖学金) (January 2026)
- Level: University-level scholarship, University of Science and Technology of China
- Xiamen University Academic Star (学术之星) (December 2021)
- Media: 🔗 University News | Feature Report
🏆 Competition Awards 3
- Jingrun Cup Mathematics Competition, First Place (October 2021)
- Category: Mathematics majors, Xiamen University
- Ranking: First Place at Xiamen University
- Reference: 🔗 Competition News
- Internet+ Innovation and Entrepreneurship Competition, Gold Medal (August 2021)
- Level: Fujian provincial competition
- Challenge Cup, First Prize (May 2021)
- Competition: National Undergraduate Academic Science and Technology Competition, Fujian provincial round


💬 Talks, Skills & Service
🎤 Talks & Presentations 3
💻 Technical Skills
🎓 Professional Service
Ad hoc reviewer for the following conferences and journals:
🎯 Hobbies & Interests

Happy to connect over music, board games, badminton, hiking, or a meal.
📬 Let's Connect
Get in Touch
📫 Email: cyd0806@mail.ustc.edu.cn
💼 I welcome research discussions and collaboration in machine learning, embodied intelligence, and connectomics.
📍 USTC Gaoxin campus, Hefei, Anhui, China